


This section covers proving an agent actually works — scoring its answers against a dataset with the metrics that matter, before and after you ship a change.
Overview
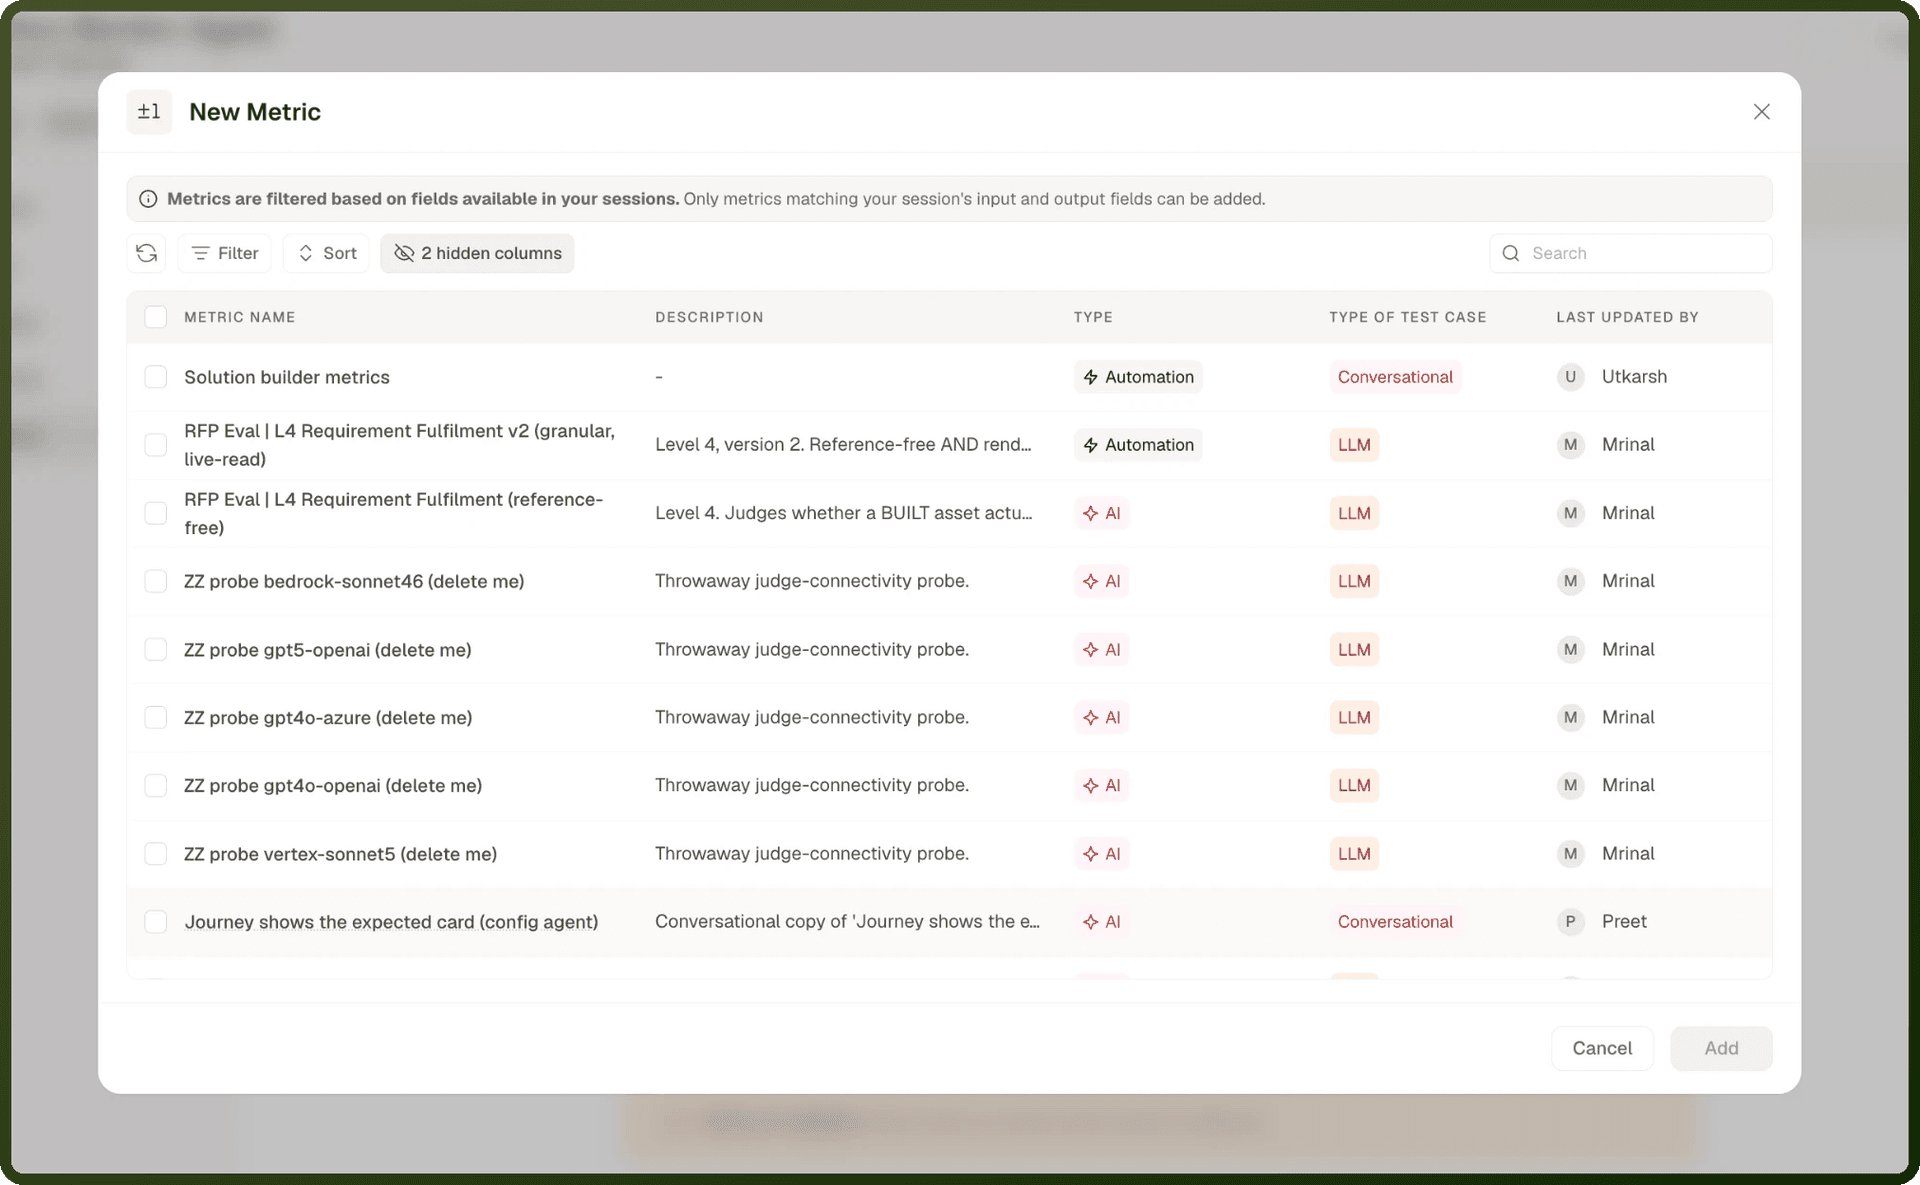
Evaluation Datasets hold the test cases — the inputs and expected outputs you'll score an agent against. Evaluation Metrics define how a case is judged: built-in library metrics like Faithfulness or Answer Relevancy, or your own AI, Automation, Human-in-the-loop, or Derived metrics. Evaluation Experiments tie them together — running a chosen agent against a dataset, scoring every case with your selected metrics, and producing a pass/fail plus cost and latency you can compare across runs.

What's in This Section
Topic | Covers |
|---|---|
Evaluation Datasets | Building the test cases an experiment runs against. |
Evaluation Metrics | Scoring answers — built-in library metrics or your own custom and derived metrics. |
Evaluation Experiments | Running an agent against a dataset, reading run results, and human annotation. |
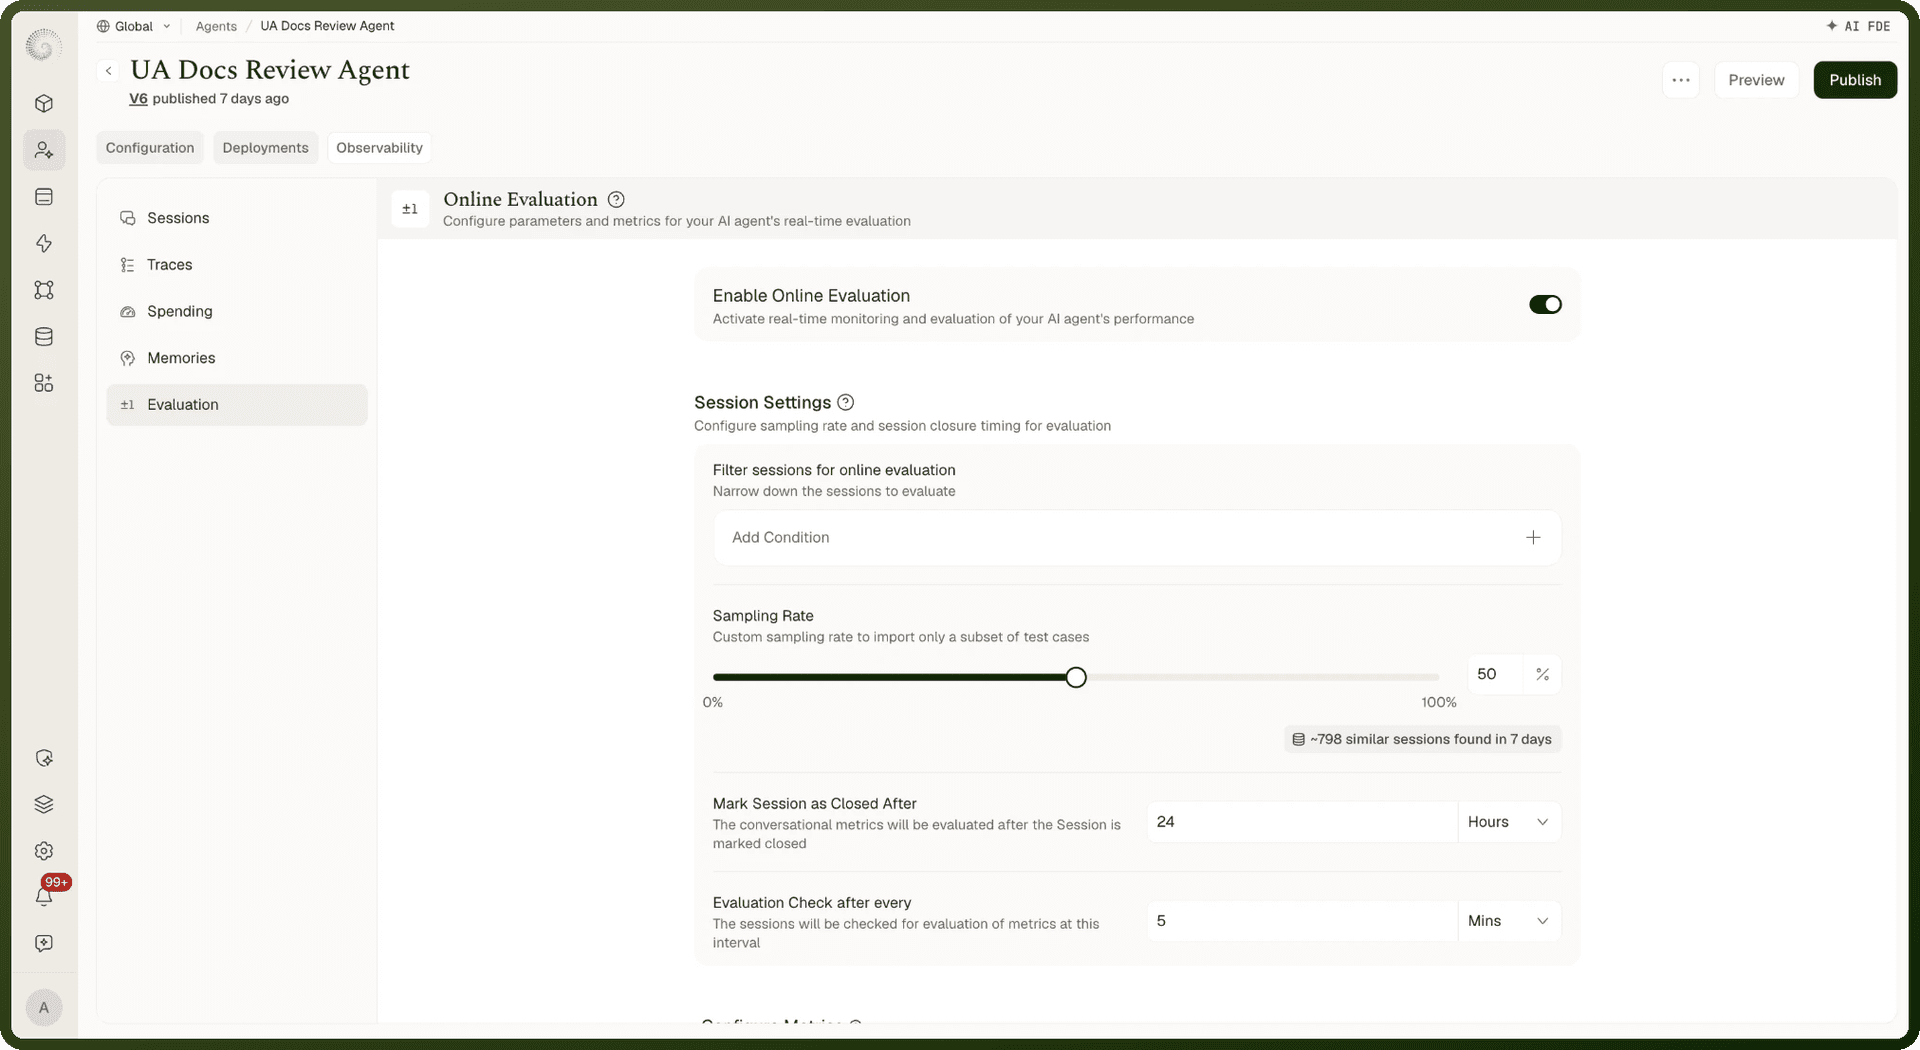
Scoring an agent's live sessions on a schedule, set up from the agent's Observability tab with Enable Online Evaluation. Experiments test against a fixed dataset; online evaluation catches quality drift in production. |
The Typical Flow
Build a Dataset, pick or author your Metrics, then run an Experiment that scores outputs against both. The outputs can come from the live agent, from outputs stored in the dataset, or from a Task automation. Use this before publishing a change to catch regressions, and rerun it after to prove the change improved quality.