


Aggregate Data groups time-series data from the analytics and reporting store into automatically sized buckets over a specified time range. The platform selects a sensible interval — minutes, hours, days, or months — based on the window you provide, so the granularity of the output adapts to the query rather than remaining fixed.
Overview
Use Aggregate Data when you need a summarized, time-bucketed view of reporting data rather than raw rows. Supply a query or data source and a time range; the platform auto-selects the bucket interval that gives a meaningful histogram for that window — a one-hour window yields minute-level buckets, while a one-year window yields monthly buckets.
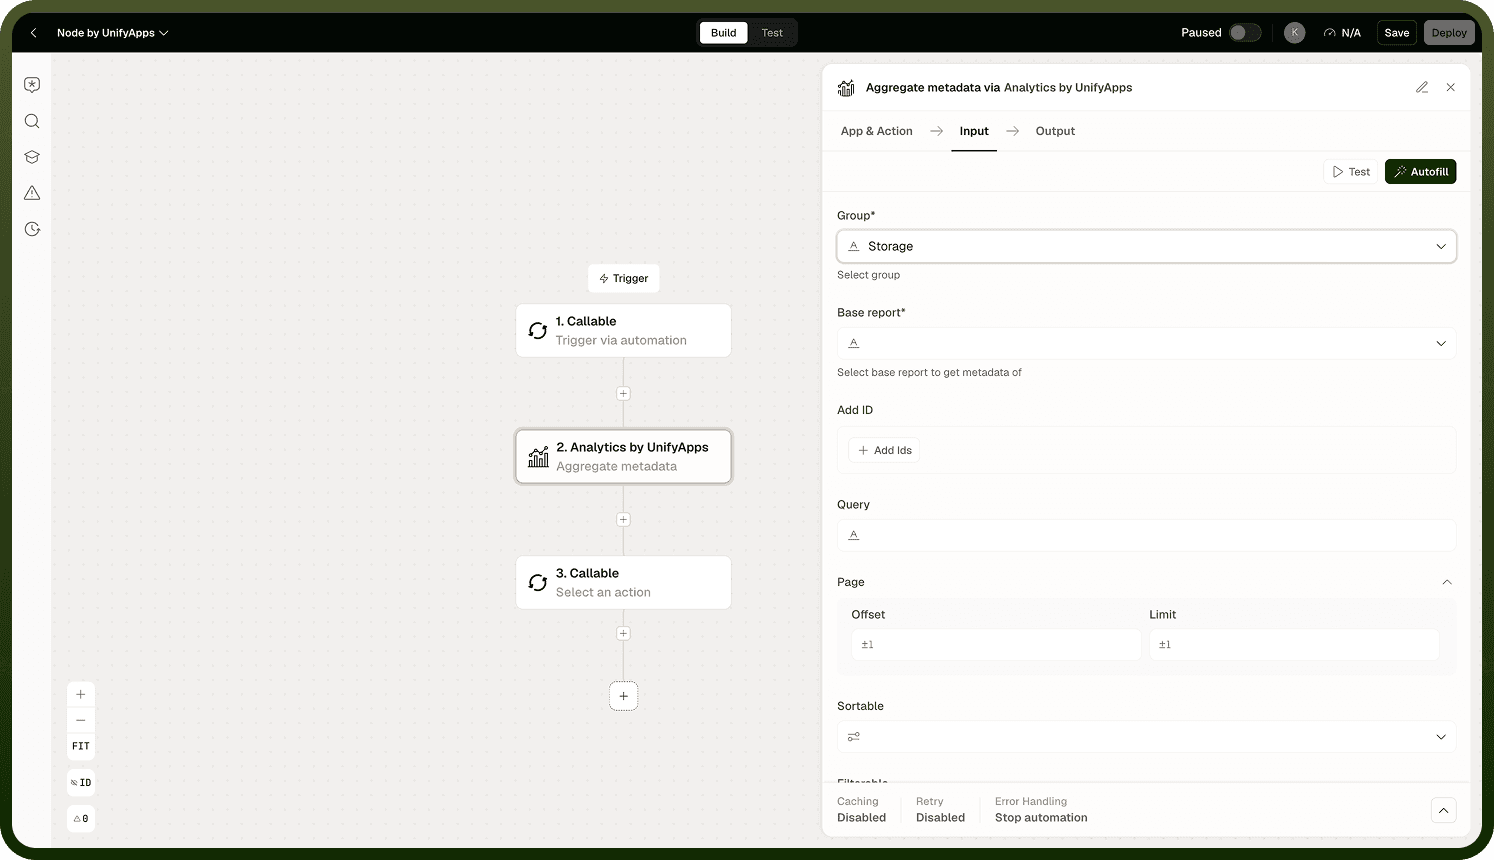
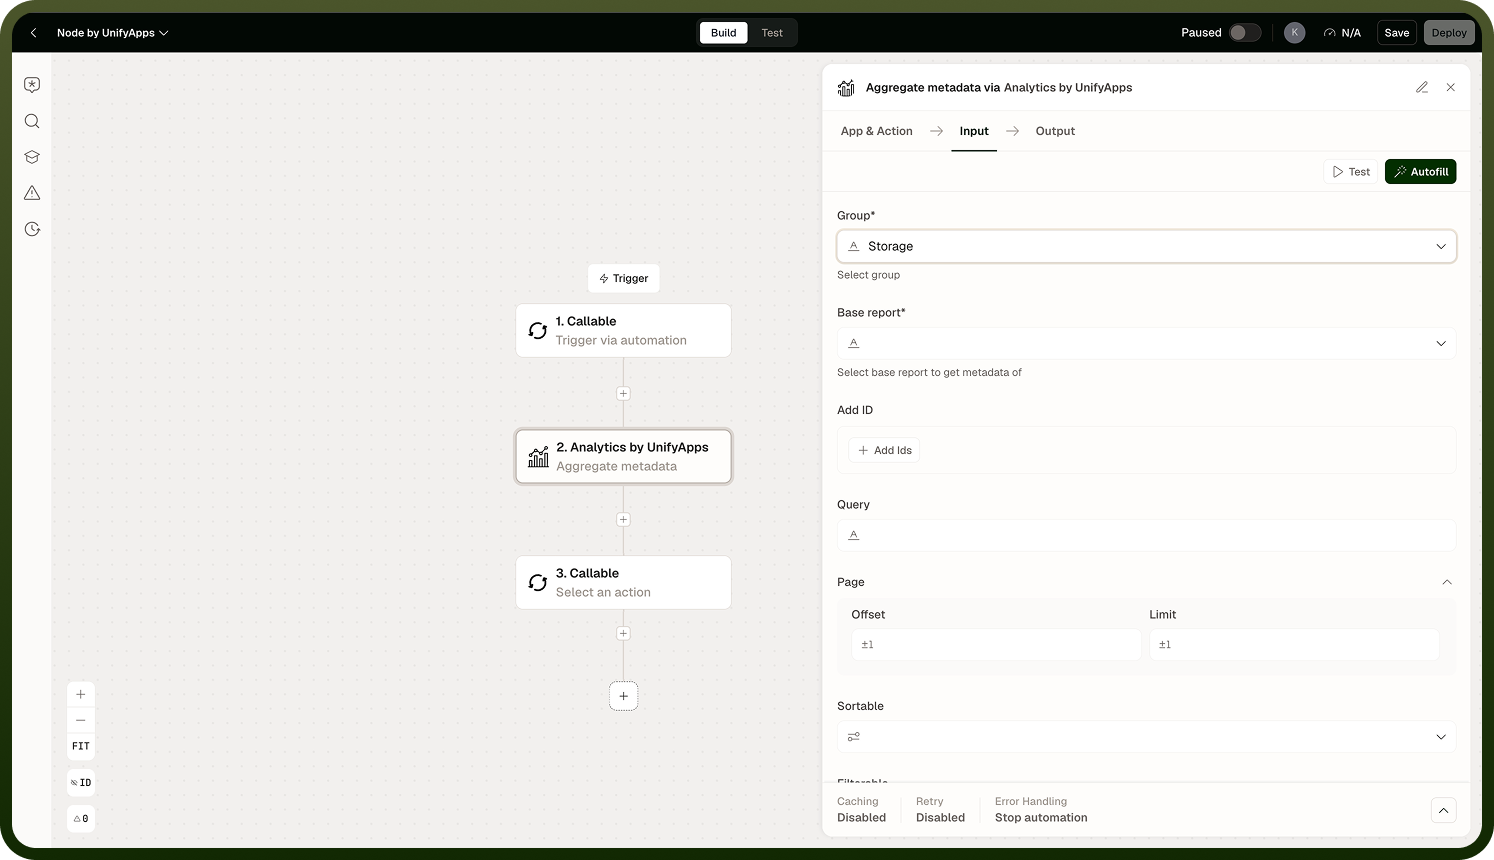
This action is well-suited to dashboard-feeding automations, trend detection, and any scenario where you need to answer "how did this metric change over time" rather than "what are the individual records." The auto-bucketing means you do not need to calculate or hardcode an interval — the platform infers it from your time range.
Bucket size adapts to the window: The aggregation interval is chosen automatically based on your time range. Expect minute-level buckets for short windows and day- or month-level buckets for longer ones. The interval is returned alongside the data so downstream nodes know the resolution.
Input
Field | Description | Required |
|---|---|---|
Query / Data Source | The SQL query or data source reference defining the time-series data to aggregate. The data must include a timestamp column the platform can use for bucketing. | * |
Time Range Start | The start of the aggregation window. Buckets begin at or after this point. | * |
Time Range End | The end of the aggregation window. Buckets end at or before this point. | * |
Aggregation Function | The function to apply within each bucket — for example, sum, count, avg, min, or max. When omitted, the platform applies a default aggregation suitable for the data type. |
Output
The action returns a time-bucketed result set:
An array of bucket objects, each containing a timestamp marking the bucket's start, the aggregated value for that bucket, and the bucket interval used.
The auto-selected interval (for example, 1h, 1d, 1mo), so downstream nodes know the resolution of the data.
Notes
Keep the following in mind when using Aggregate Data.
The bucket interval is chosen automatically by the platform based on the time range. You cannot force a specific interval — design your downstream logic to consume whatever interval the platform selects.
Bucket size will differ between runs if the time range changes — a query run today over the last 7 days will produce different granularity than the same query run over the last 365 days.
The aggregation function applies within each bucket. If no function is specified, a platform default is used — confirm the default matches your intent before deploying.
This action runs against the analytics and reporting store — not the workflow-log store. For aggregating log data over time, use LogQL actions.
For large time ranges, the number of buckets returned remains manageable because the interval widens — you will not receive thousands of minute-level buckets for a year-long query.
If your downstream visualization or logic depends on a fixed interval, test the aggregation output across the full range of time windows your automation will encounter. The interval may change between runs as the window shifts.